project
AWS security chatbot
A serverless assistant that answers security questions from a sample company policy file mapped to NIST CSF 2.0, NIS2, DORA and CMMC 2.0, and what I would change about it now.
- AWS Lambda
- SageMaker
- S3
- IAM
- Python
What it does
You send it a security question. It answers using a reference file about a fictional company, Acme Corporation, whose security program is mapped to NIST CSF 2.0, NIS2, DORA and CMMC 2.0.
It is a Python Lambda function that takes {"user_input": "..."} and returns a JSON response. There is no front end. I tested it with Lambda test events.
One note on terms. The repo README calls this RAG, and at the time I thought it was. Looking back, it is not. There is no search, no embeddings and no vector store. The whole reference file goes into every prompt. “Context injection” or “grounding with a reference file” is the honest name. A real RAG version would retrieve only the chunks that matter for the question.
How it works
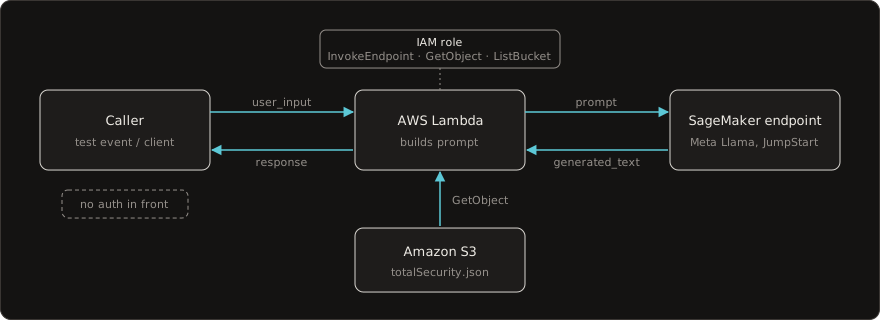
- The caller sends a test event with a
user_inputfield. - Lambda reads
totalSecurity.jsonfrom an S3 bucket withGetObject. - Lambda builds one prompt: the question, then a role block that tells the model to act as a professional cybersecurity assistant and cite those four frameworks, then the entire JSON file.
- Lambda calls a SageMaker JumpStart endpoint running a Meta Llama text-generation model, with temperature 0.2 and
max_new_tokens300. It returnsgenerated_textin a 200 response, or the error string in a 500.
What it gets right
The Lambda role only has three permissions: sagemaker:InvokeEndpoint, s3:GetObject and s3:ListBucket. That is least privilege.
Temperature is 0.2, so the same question gets close to the same answer. For compliance questions, that matters more than variety.
Answers also come from a known dataset instead of whatever the model remembers. In the demo, the model answered from Acme’s ransomware containment policy, not from generic advice.
What I’d change now
I built this in 2025, before my co-op on Kroger’s AI security team. Don’t get me wrong, it works, and it did what I set out to do. It would not pass a security review, though. Here is what I would change, starting with what I would catch first today.
Prompt order. User input goes into the prompt before the system instructions. I did not think about ordering at all when I wrote it. Now it is the first thing I check, because this order makes prompt injection easy. Fix: put the system prompt first, delimit the user input clearly, and use the model’s chat template.
Raw errors in the response. The 500 path returns the raw exception text to the caller. That can leak internal details to whoever called it. Fix: log details server-side and return a generic error with a request ID.
Raw model output in logs. Every call prints the full SageMaker response to CloudWatch. Fix: log metadata only (request ID, latency, status) and redact the rest.
Nothing in front of the Lambda. No API Gateway, no auth, no rate limiting. Right now it only runs from the console. Opening it to real users like this would let anyone who reaches it run up the SageMaker bill. Fix: API Gateway with IAM or Cognito auth, plus throttling.
The whole dataset in every prompt. It wastes tokens and will not scale past a small file. Fix: chunk the data, embed it, and retrieve the top matches, which is real RAG. I would add per-document access tags so retrieval respects who is asking.
No chat template or stop sequence. In the demo, the model keeps writing extra turns on its own and role-plays a CISO and a user going back and forth. Fix: use the Llama chat format and set stop tokens.
What I learned
The model was not the weak part. Every real security problem was in the glue code around it: prompt order, error handling, logging, and an open front door. A prompt is an input boundary, and back then I treated it like a string template.
It is also why agent security interests me. If a simple Lambda has six holes, an agent with tools has more.
← Back to all projects